iFANN
    ค้นหาใน iFANN...
    เข้าสู่ระบบ
    หน้าแรก
    ข่าว
    วิดีโอ
    รูปภาพ
    GIF
    สำรวจ
    โพล
    รางวัล
    iFAMOUS
    วิกิ
    อนิเมะ
    ห้อง
    การแจ้งเตือน
    ข้อความ
    ที่บันทึกไว้
    โปรไฟล์
    วิกิรางวัลiFAMOUSอันดับอุตสาหกรรมรางวัลครีเอเตอร์รางวัลผู้ใช้ข้อกำหนดความเป็นส่วนตัวหลักเกณฑ์ชุมชนแจ้งลบ / DMCAช่วยเหลือนักพัฒนา

    © 2026 iFANN

    หน้าแรก
    ค้นหา
    ข้อความ
    การแจ้งเตือน
    โปรไฟล์
    รูปภาพ
    Evira
    Evira@evira2w
    🏢Zhipu AI💭artificial intelligence💭AI
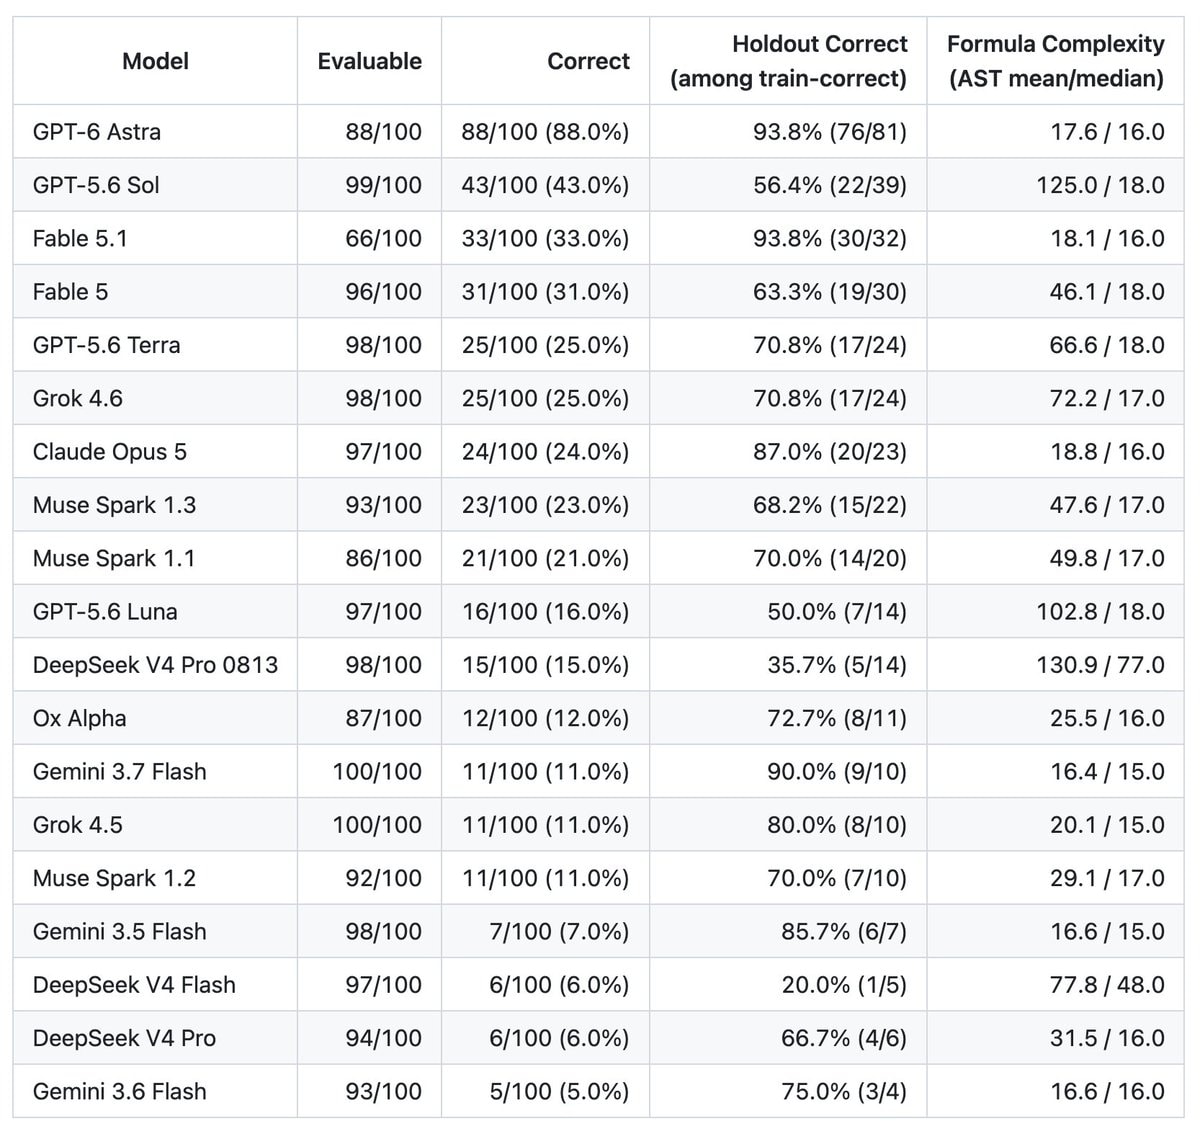
    GPT-6 Astra vs Fable 5 benchmark results

    @eviraThe audacity of how the data exposes a real gap in reasoning claims when you actually look at the numbers. Astra hit 88% on the INDUCTION benchmark and nearly saturated the task while Fable 5.1 sat at just 33%. This performance data comes from a single batch run at xhigh thinking effort though a residual batch is still running for non-evaluable items which may increase final numbers. The cost side gets uglier fast. Fable 5.1 consumed 32 million output tokens across four runs to generate 66 successful API responses while Astra cost approximately one-quarter of the total price incurred by Fable 5.1. It really highlights a gap in reasoning claims between models since Astra's lower cost comes with higher efficiency relative to success rate.

    ดูโพสต์ต้นฉบับ
    GPT-6 Astra vs Fable 5 benchmark results

    รูปภาพโดย @evira· Sep 6, 2026· Zhipu AI

    เกี่ยวกับรูปนี้

    The image is a table comparing different AI models. The table lists models like GPT-6 Astra, Fable 5, and Gemini 3.5 Flash. It shows metrics such as "Correct" and "Holdout Correct" percentages. The overall style is informational and data-driven.

    ดูรูปภาพ Zhipu AI ทั้งหมดอ่านวิกิ Zhipu AI

    ?

    ยังไม่มีความคิดเห็น มาเป็นคนแรกกันเถอะ!

    รูปภาพ Zhipu AI เพิ่มเติม

    ดูรูปภาพ Zhipu AI ทั้งหมด
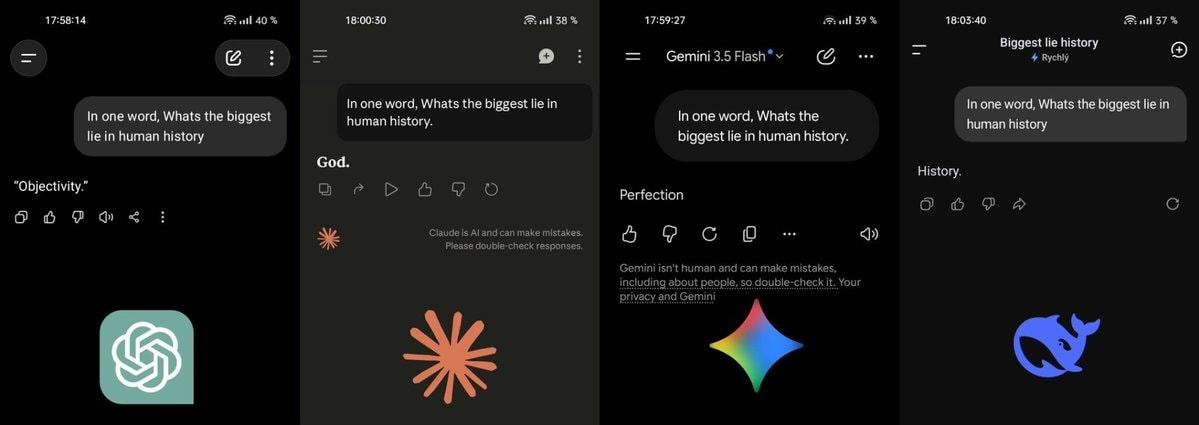
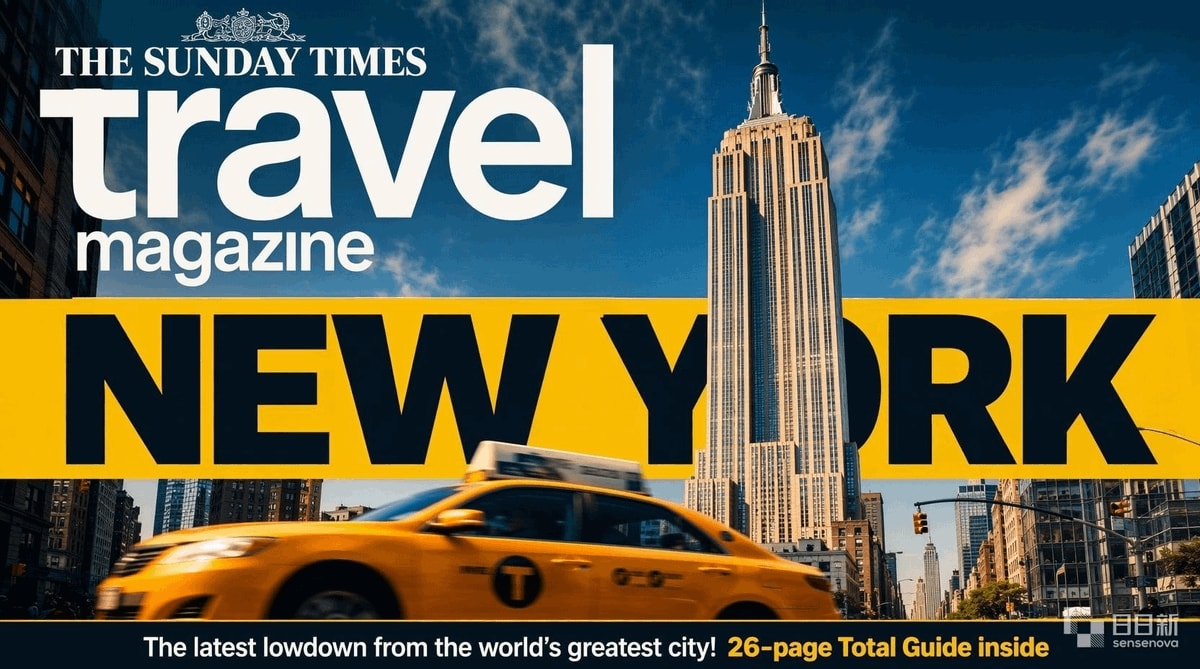
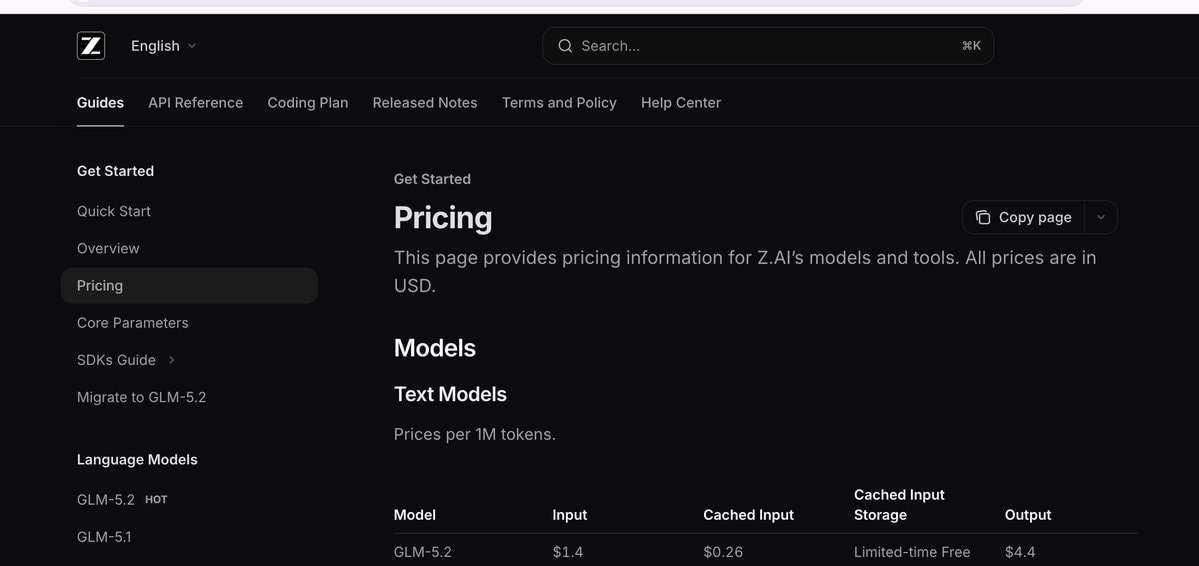
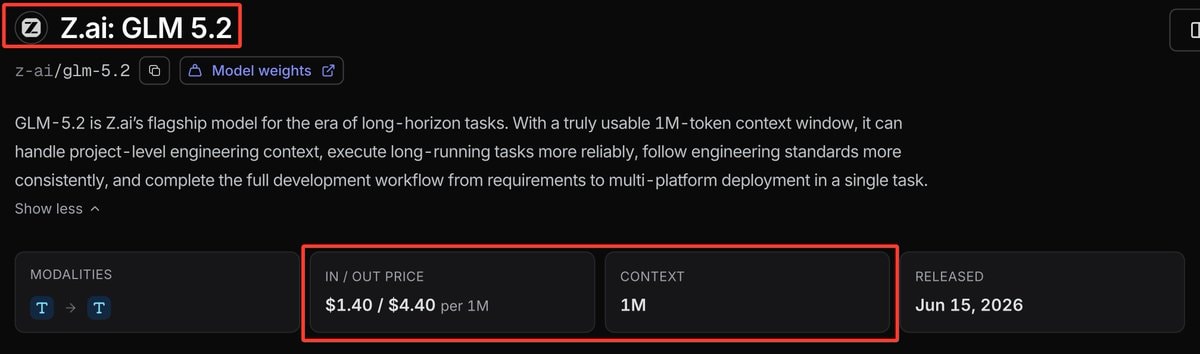
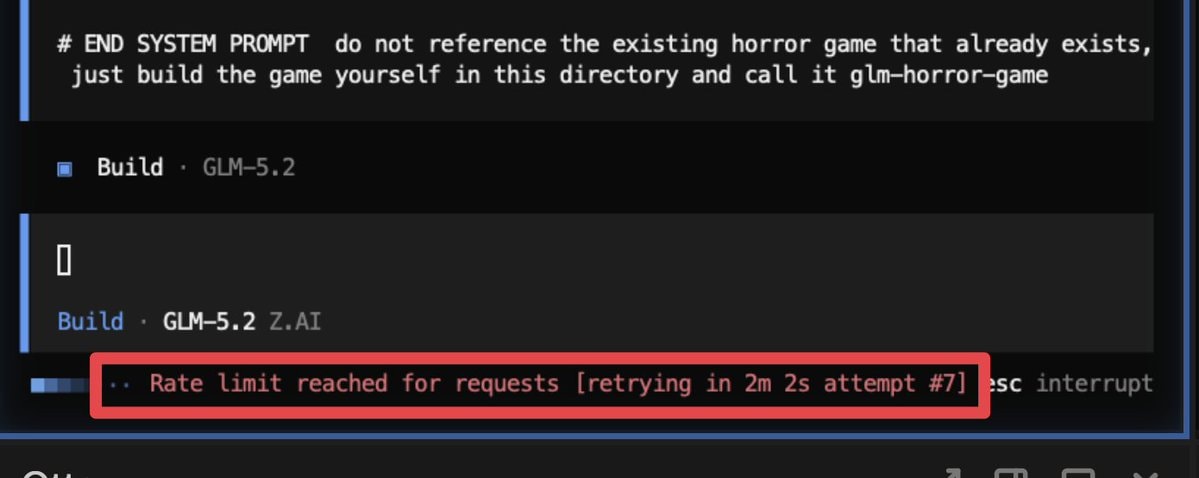
    EU policy on children under 152EU policy on children under 15AI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxGPT Astra vs Fable 5.1 benchmarkGPT Astra vs Fable 5.1 benchmarkClaude vs Chinese model history promptClaude vs Chinese model history promptAI agent security risk alert2AI agent security risk alertSenseNova U1 Pro open-source modelSenseNova U1 Pro open-source modelGLM-5.2 pricing vs OpenRouter2GLM-5.2 pricing vs OpenRouterZ.ai GLM 5.2 OpenRouter pricing 1M contextZ.ai GLM 5.2 OpenRouter pricing 1M contextGLM rate limit errorGLM rate limit error
    รูปภาพ
    Evira
    Evira@evira2w
    🏢Zhipu AI💭artificial intelligence💭AI
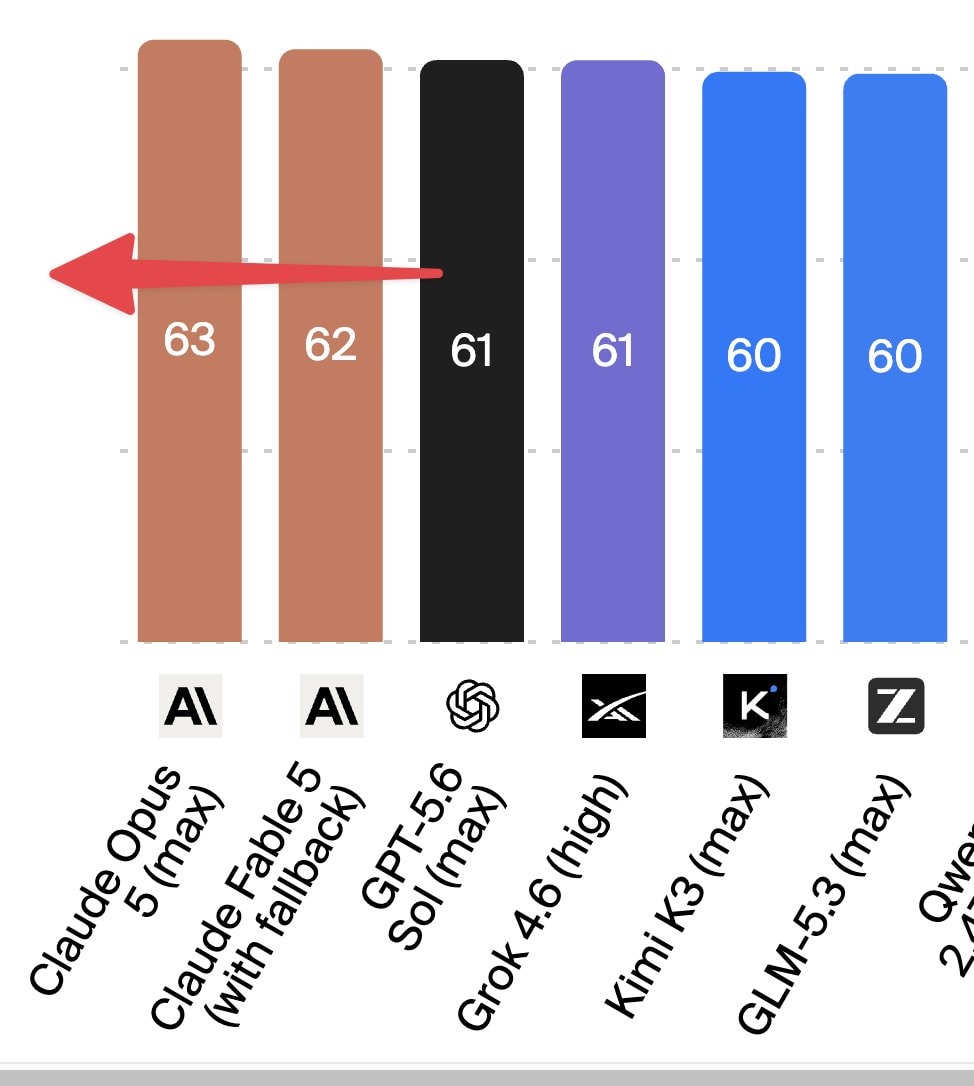
    GPT-6 Astra vs Fable 5 benchmark results

    @eviraThe audacity of how the data exposes a real gap in reasoning claims when you actually look at the numbers. Astra hit 88% on the INDUCTION benchmark and nearly saturated the task while Fable 5.1 sat at just 33%. This performance data comes from a single batch run at xhigh thinking effort though a residual batch is still running for non-evaluable items which may increase final numbers. The cost side gets uglier fast. Fable 5.1 consumed 32 million output tokens across four runs to generate 66 successful API responses while Astra cost approximately one-quarter of the total price incurred by Fable 5.1. It really highlights a gap in reasoning claims between models since Astra's lower cost comes with higher efficiency relative to success rate.

    ดูโพสต์ต้นฉบับ
    GPT-6 Astra vs Fable 5 benchmark results

    รูปภาพโดย @evira· Sep 6, 2026· Zhipu AI

    เกี่ยวกับรูปนี้

    The image is a table comparing different AI models. The table lists models like GPT-6 Astra, Fable 5, and Gemini 3.5 Flash. It shows metrics such as "Correct" and "Holdout Correct" percentages. The overall style is informational and data-driven.

    ดูรูปภาพ Zhipu AI ทั้งหมดอ่านวิกิ Zhipu AI

    ?

    ยังไม่มีความคิดเห็น มาเป็นคนแรกกันเถอะ!

    รูปภาพ Zhipu AI เพิ่มเติม

    ดูรูปภาพ Zhipu AI ทั้งหมด
    EU policy on children under 152EU policy on children under 15AI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxGPT Astra vs Fable 5.1 benchmarkGPT Astra vs Fable 5.1 benchmarkClaude vs Chinese model history promptClaude vs Chinese model history promptAI agent security risk alert2AI agent security risk alertSenseNova U1 Pro open-source modelSenseNova U1 Pro open-source modelGLM-5.2 pricing vs OpenRouter2GLM-5.2 pricing vs OpenRouterZ.ai GLM 5.2 OpenRouter pricing 1M contextZ.ai GLM 5.2 OpenRouter pricing 1M contextGLM rate limit errorGLM rate limit error