iFANN
    ค้นหาใน iFANN...
    เข้าสู่ระบบ
    หน้าแรก
    ข่าว
    วิดีโอ
    รูปภาพ
    GIF
    สำรวจ
    โพล
    รางวัล
    iFAMOUS
    วิกิ
    อนิเมะ
    ห้อง
    การแจ้งเตือน
    ข้อความ
    ที่บันทึกไว้
    โปรไฟล์
    วิกิรางวัลiFAMOUSอันดับอุตสาหกรรมรางวัลครีเอเตอร์รางวัลผู้ใช้ข้อกำหนดความเป็นส่วนตัวหลักเกณฑ์ชุมชนแจ้งลบ / DMCAช่วยเหลือนักพัฒนา

    © 2026 iFANN

    หน้าแรก
    ค้นหา
    ข้อความ
    การแจ้งเตือน
    โปรไฟล์
    รูปภาพ
    Estebankiwi
    Estebankiwi@estebankiwi3mo
    📱GPT💭AI💭Tech
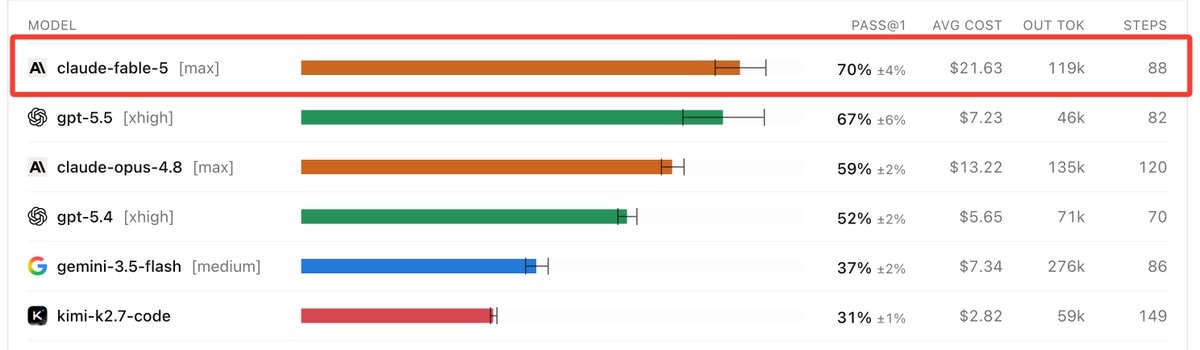
    Claude Fable 5 DeepSWE benchmark

    @estebankiwiClaude Fable 5 has claimed the top spot on DeepSWE with a score of 70%. However, the performance gap between Fable 5 and GPT 5.5 is far more significant than just three percentage points. Fable 5 generates code that reads as if it were written by a senior engineer, while GPT 5.5 produces code that simply passes the tests. Both models deliver functional software, but only one delivers software that truly impresses.

    ดูโพสต์ต้นฉบับ
    Claude Fable 5 DeepSWE benchmark

    รูปภาพโดย @estebankiwi· Jun 19, 2026· GPT

    เกี่ยวกับรูปนี้

    The image shows a horizontal bar chart comparing AI models. The focus is on a table with model names, performance metrics, and bars representing their performance. The model "claude-fable-5" is highlighted with a red rectangle around it and its corresponding bar is orange. The table columns are labeled "MODEL", "PASS@1", "AVG COST", "OUT TOK", and "STEPS". The model names listed are claude-fable-5, gpt-5.5, claude-opus-4.8, gpt-5.4, gemini-3.5-flash, and kimi-k2.7-code. No on-screen text stands out aside from the column headers and model names.

    ดูรูปภาพ GPT ทั้งหมดอ่านวิกิ GPT

    ?

    รูปภาพ GPT เพิ่มเติม

    ดูรูปภาพ GPT ทั้งหมด
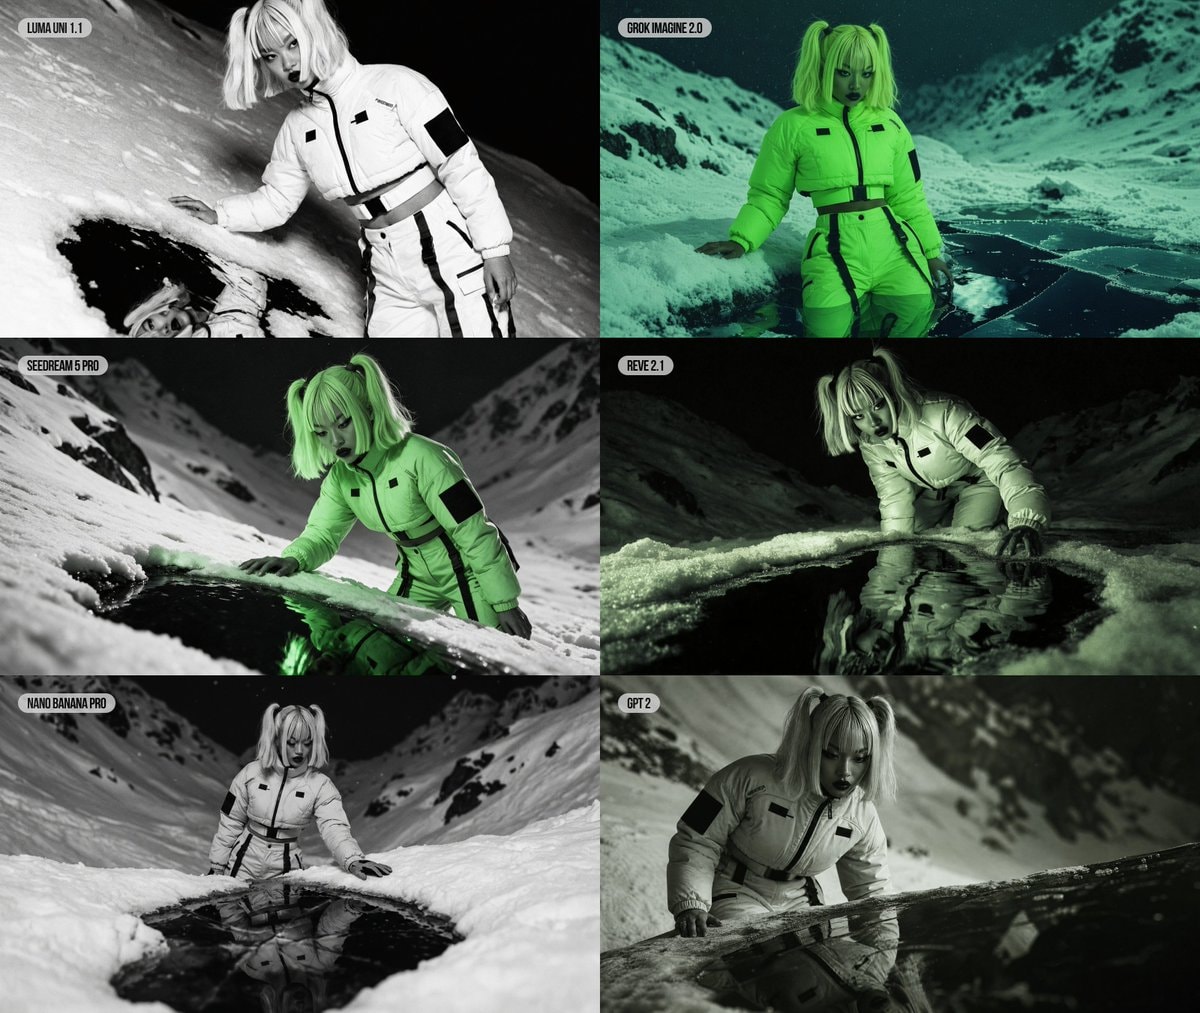
    AI as your doctor?AI as your doctor?GPT 6 Astra effort comparison tableGPT 6 Astra effort comparison tablemanual coding psychopathmanual coding psychopathJensen Huang AGI has arrived GPT-6 Astra2Jensen Huang AGI has arrived GPT-6 AstraAI Breakfast greatest predictionAI Breakfast greatest predictionweekend plans cancelledweekend plans cancelledAI Image Models ComparisonAI Image Models Comparison
    รูปภาพ
    Estebankiwi
    Estebankiwi@estebankiwi3mo
    📱GPT💭AI💭Tech
    Claude Fable 5 DeepSWE benchmark

    @estebankiwiClaude Fable 5 has claimed the top spot on DeepSWE with a score of 70%. However, the performance gap between Fable 5 and GPT 5.5 is far more significant than just three percentage points. Fable 5 generates code that reads as if it were written by a senior engineer, while GPT 5.5 produces code that simply passes the tests. Both models deliver functional software, but only one delivers software that truly impresses.

    ดูโพสต์ต้นฉบับ
    Claude Fable 5 DeepSWE benchmark

    รูปภาพโดย @estebankiwi· Jun 19, 2026· GPT

    เกี่ยวกับรูปนี้

    The image shows a horizontal bar chart comparing AI models. The focus is on a table with model names, performance metrics, and bars representing their performance. The model "claude-fable-5" is highlighted with a red rectangle around it and its corresponding bar is orange. The table columns are labeled "MODEL", "PASS@1", "AVG COST", "OUT TOK", and "STEPS". The model names listed are claude-fable-5, gpt-5.5, claude-opus-4.8, gpt-5.4, gemini-3.5-flash, and kimi-k2.7-code. No on-screen text stands out aside from the column headers and model names.

    ดูรูปภาพ GPT ทั้งหมดอ่านวิกิ GPT

    ?

    รูปภาพ GPT เพิ่มเติม

    ดูรูปภาพ GPT ทั้งหมด
    AI as your doctor?AI as your doctor?GPT 6 Astra effort comparison tableGPT 6 Astra effort comparison tablemanual coding psychopathmanual coding psychopathJensen Huang AGI has arrived GPT-6 Astra2Jensen Huang AGI has arrived GPT-6 AstraAI Breakfast greatest predictionAI Breakfast greatest predictionweekend plans cancelledweekend plans cancelledAI Image Models ComparisonAI Image Models Comparison