iFANN
    ค้นหาใน iFANN...
    เข้าสู่ระบบ
    หน้าแรก
    ข่าว
    วิดีโอ
    รูปภาพ
    GIF
    สำรวจ
    โพล
    รางวัล
    iFAMOUS
    วิกิ
    อนิเมะ
    ห้อง
    การแจ้งเตือน
    ข้อความ
    ที่บันทึกไว้
    โปรไฟล์
    วิกิรางวัลiFAMOUSอันดับอุตสาหกรรมรางวัลครีเอเตอร์รางวัลผู้ใช้ข้อกำหนดความเป็นส่วนตัวหลักเกณฑ์ชุมชนแจ้งลบ / DMCAช่วยเหลือนักพัฒนา

    © 2026 iFANN

    หน้าแรก
    ค้นหา
    ข้อความ
    การแจ้งเตือน
    โปรไฟล์
    รูปภาพ
    Hype Castle27
    Hype Castle27@hype_castle273mo
    🎮Claude🏢DeepSeek📱Qwen
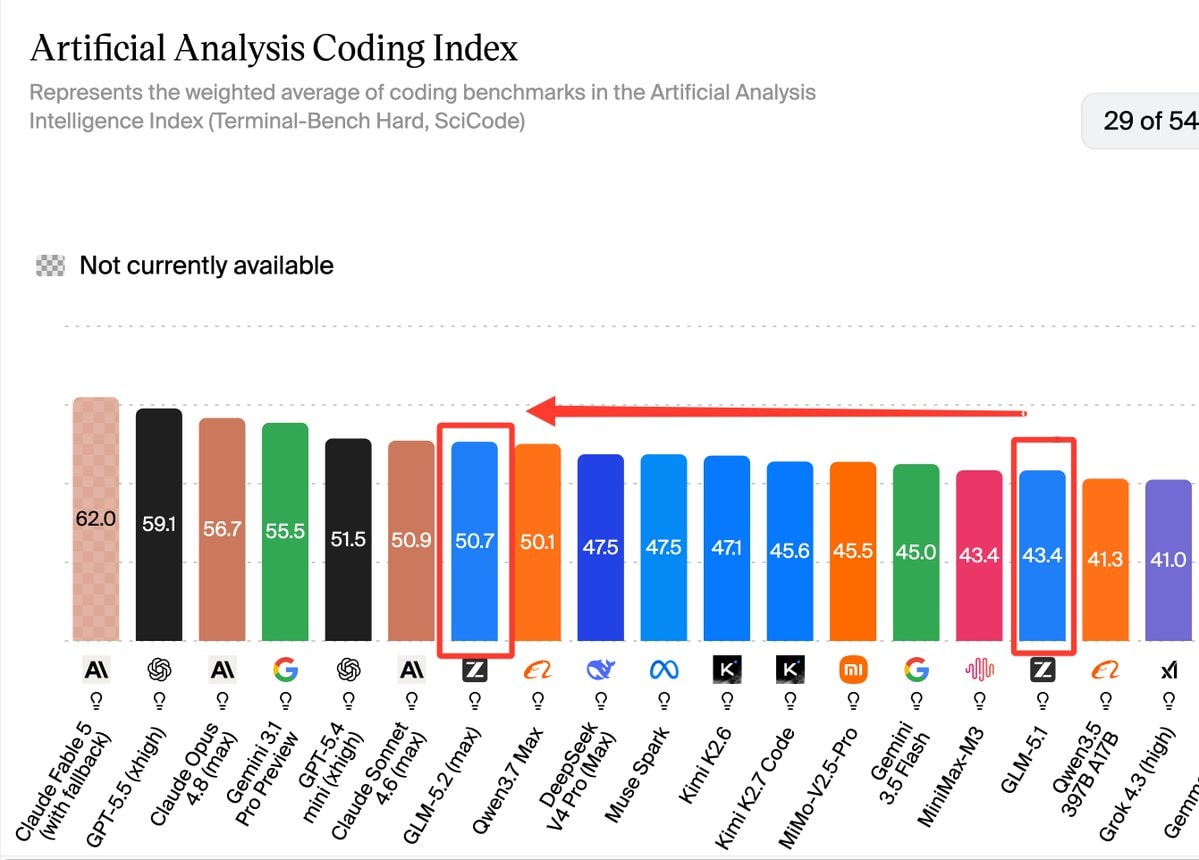
    GLM 5.2 Artificial Analysis Coding Index

    @hype_castle27GLM 5.2 has surged on the Artificial Analysis Coding Index, jumping from 43.4 to 50.7 , a gain of seven points in a single release. According to bridgemindai, these results align with what they're observing on BridgeBench and in their own personal tests. With this update, GLM 5.2 is now outperforming Qwen 3.7 Max, DeepSeek V4 Pro, and Kimi.

    ดูโพสต์ต้นฉบับ
    GLM 5.2 Artificial Analysis Coding Index

    รูปภาพโดย @hype_castle27· Jun 17, 2026· Claude

    เกี่ยวกับรูปนี้

    A horizontal bar chart titled Artificial Analysis Coding Index compares AI models on a weighted average of coding benchmarks. Two blue bars stand out with red boxes around them, one labeled Z under Owen3.7 Max scoring 50.7 and another Z model named GLM-5.1 at 43.4. A long red arrow points from right to left toward the first boxed blue bar. The linker's team logos appear beneath each bar with model names like Claude Sonnet 4.6, GPT-5.4 mini, and Grok 4.3.

    ดูรูปภาพ Claude ทั้งหมดอ่านวิกิ Claude

    ?

    รูปภาพ Claude เพิ่มเติม

    ดูรูปภาพ Claude ทั้งหมด
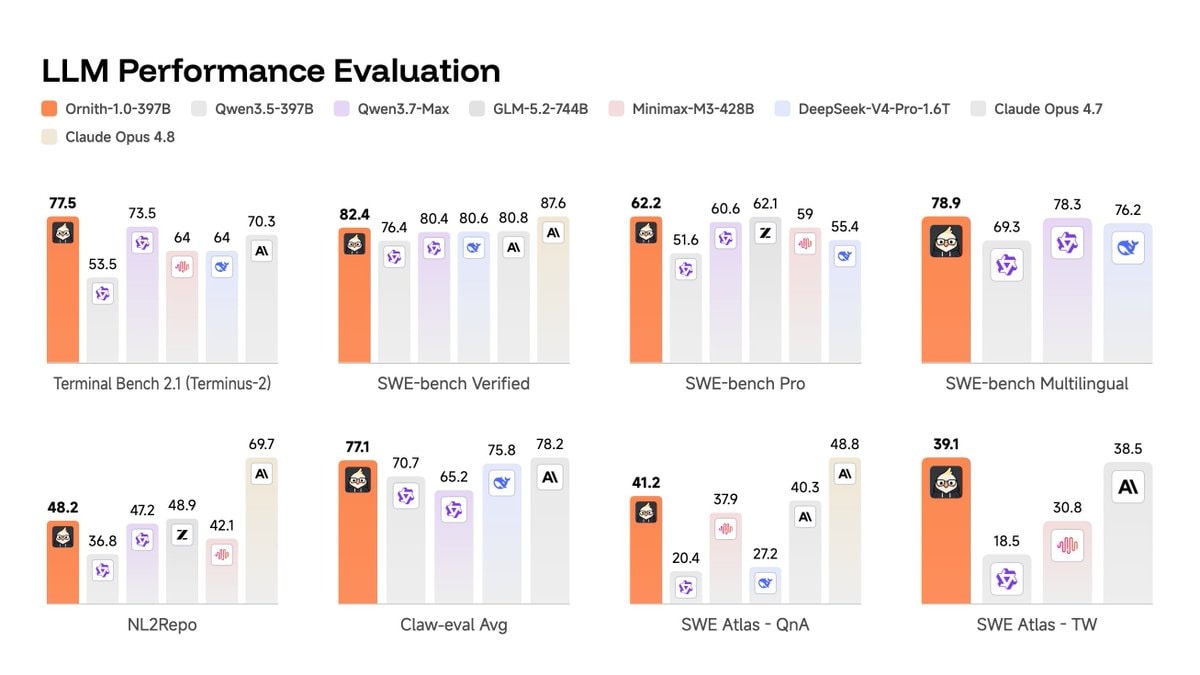
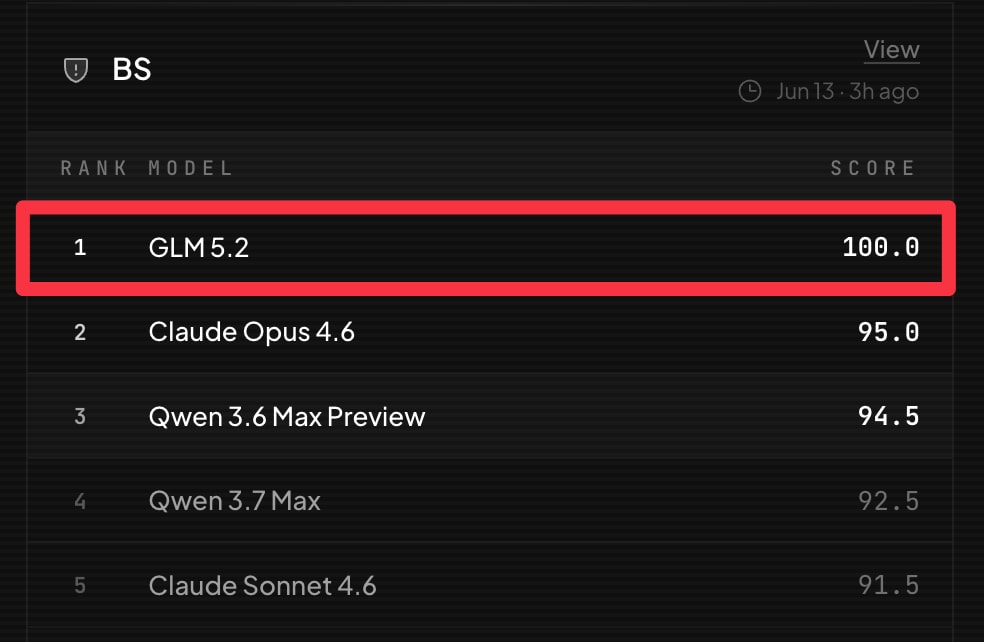
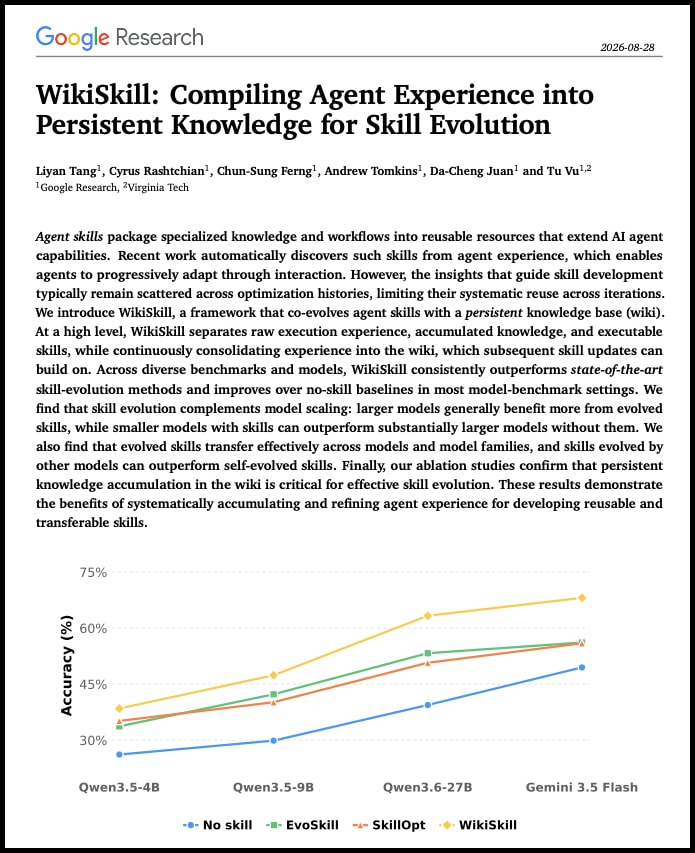
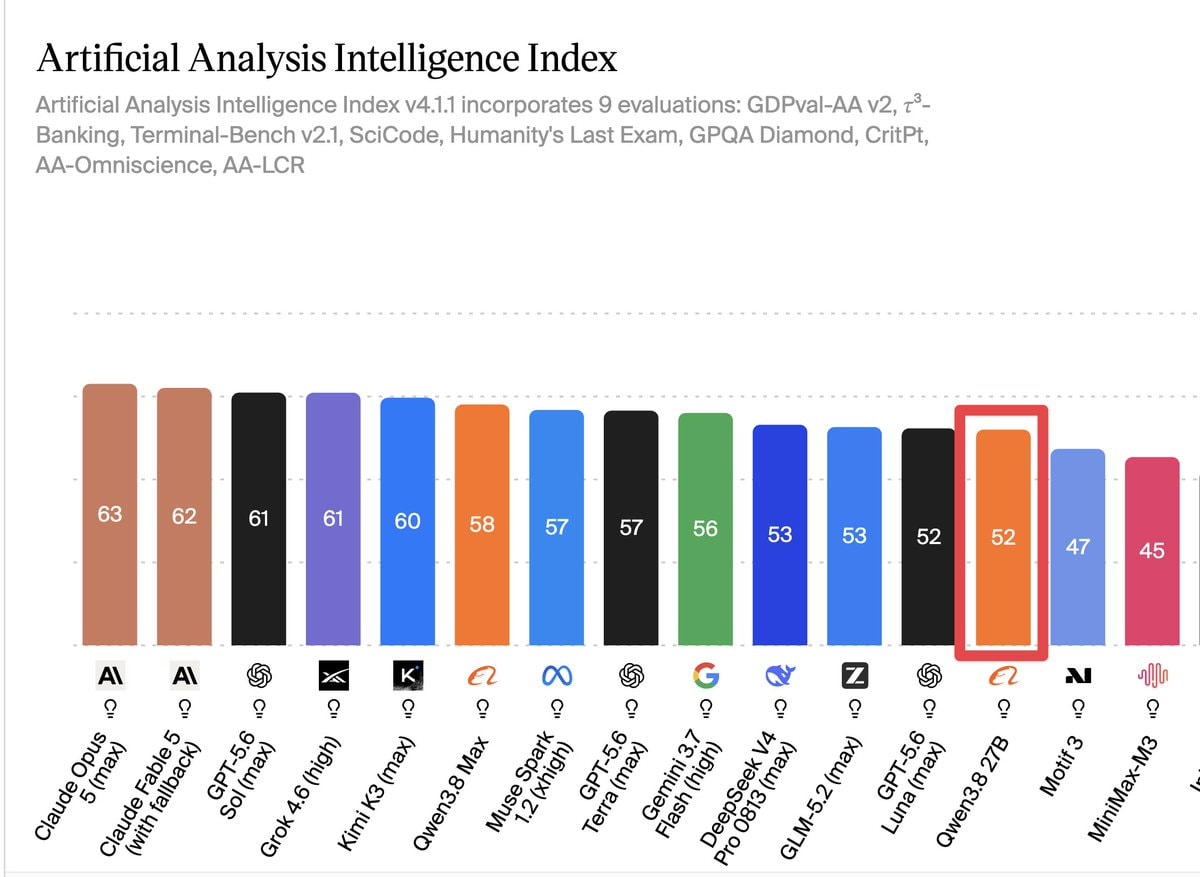
    Google WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreOrnith-1.0 agentic coding LLM performanceOrnith-1.0 agentic coding LLM performanceGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS
    รูปภาพ
    Hype Castle27
    Hype Castle27@hype_castle273mo
    🎮Claude🏢DeepSeek📱Qwen
    GLM 5.2 Artificial Analysis Coding Index

    @hype_castle27GLM 5.2 has surged on the Artificial Analysis Coding Index, jumping from 43.4 to 50.7 , a gain of seven points in a single release. According to bridgemindai, these results align with what they're observing on BridgeBench and in their own personal tests. With this update, GLM 5.2 is now outperforming Qwen 3.7 Max, DeepSeek V4 Pro, and Kimi.

    ดูโพสต์ต้นฉบับ
    GLM 5.2 Artificial Analysis Coding Index

    รูปภาพโดย @hype_castle27· Jun 17, 2026· Claude

    เกี่ยวกับรูปนี้

    A horizontal bar chart titled Artificial Analysis Coding Index compares AI models on a weighted average of coding benchmarks. Two blue bars stand out with red boxes around them, one labeled Z under Owen3.7 Max scoring 50.7 and another Z model named GLM-5.1 at 43.4. A long red arrow points from right to left toward the first boxed blue bar. The linker's team logos appear beneath each bar with model names like Claude Sonnet 4.6, GPT-5.4 mini, and Grok 4.3.

    ดูรูปภาพ Claude ทั้งหมดอ่านวิกิ Claude

    ?

    รูปภาพ Claude เพิ่มเติม

    ดูรูปภาพ Claude ทั้งหมด
    Google WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreOrnith-1.0 agentic coding LLM performanceOrnith-1.0 agentic coding LLM performanceGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS